

Industry: Engineering
Product: ModelRisk
Application: Quantifying the Statistical Power of a Proof-Test Qualification Program
A Zero-Failure Test on 20 Units Still Lets One Sub-Target Lot in Twenty Pass
A pressure-vessel supplier qualified each production lot the conventional way: proof-test 20 units at 1.25× design load, accept the lot if none fail. The contract required a demonstrated reliability of R ≥ 0.999 at design load. Passing the test felt like proving the target had been met. The reliability engineer asked the question the pass/fail rule cannot answer: of the lots that pass this test, how many are actually below 0.999? The Monte Carlo answer was 4.9% — about one passing lot in twenty is a sub-target lot that slipped through. Worse, the same test was rejecting 38% of genuinely good lots. The qualification program was simultaneously too weak to catch bad lots and too harsh on good ones.
This is not a statement about any single vessel's stress margin — it is a statement about the test program's statistical power. The team modelled the whole qualification scheme in ModelRisk: an uncertain population of lots, a proof test applied to each, and the gap between what the test demonstrates and what is actually true.
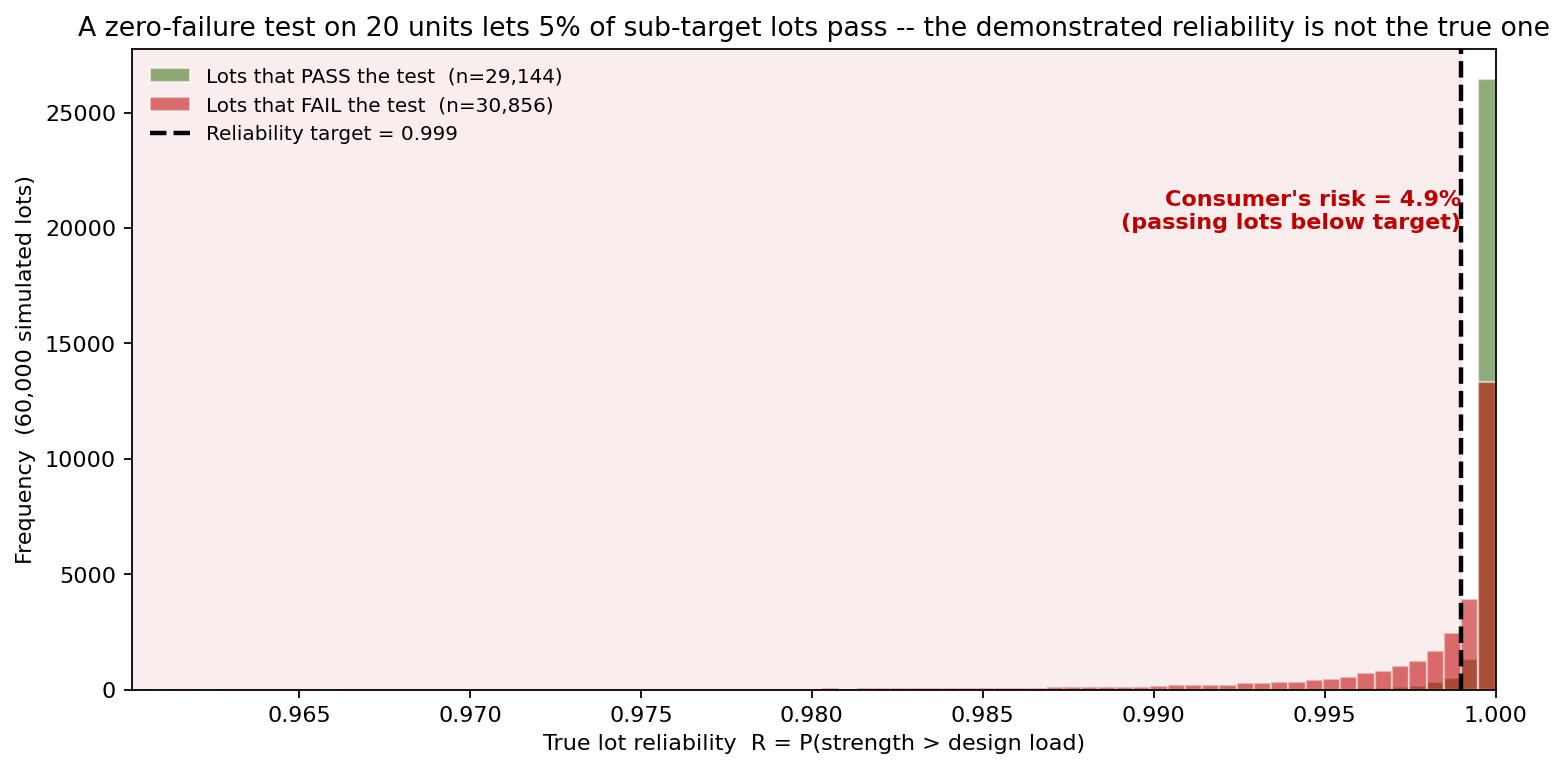
The key realism is that the vendor ships a population of lots, each with its own true reliability — median strength wanders around 1.55× design load and the coefficient of variation around 12%, lot to lot. The histogram splits those lots by test outcome. Lots that pass have a mean true reliability of 0.99980; lots that fail average 0.99708. But the two groups overlap, and the overlap to the left of the 0.999 target is the consumer's risk: sub-target lots that passed anyway. With a zero-failure test on 20 units, that overlap is 4.9% of all passing lots.
How a proof test "demonstrates" reliability
A unit survives the proof test if its true strength exceeds the proof load — a Bernoulli outcome whose probability p = P(strength > proof load) is governed by the lot's (uncertain) strength distribution. The number of failures in a lot of N units is then Binomial(N, 1−p), and the lot is accepted under a zero-failure plan if that count is zero. The classic reliability-demonstration identity follows directly: for a zero-failure plan, the probability a marginal lot passes is p^N.
Each lot's true design-load reliability and its proof-pass probability are both derived from a LogNormal strength model whose median and CV are themselves drawn per lot. Modelling the lot quality as uncertain — rather than assuming every lot is the nominal "good" lot — is what makes consumer's and producer's risk meaningful quantities rather than zero by assumption.
Why a pass/fail verdict fails here
A single pass/fail outcome is one Bernoulli draw on top of an uncertain lot. It carries no statement of how discriminating the test is. A test can pass for two completely different reasons — the lot is genuinely strong, or the lot is marginal and 20 units happened not to find the weak one. The deterministic mindset ("it passed, therefore R ≥ 0.999") cannot separate them. Only by simulating across the population of lots, and tracking each lot's true reliability alongside its test outcome, do the two risks become visible:
- Consumer's risk — a sub-target lot passes: 4.9%
- Producer's risk — a genuinely good lot (R ≥ 0.999) fails: 38.3%
The 38% producer's risk is the finding that surprised the team: a 1.25× proof factor with a zero-failure rule is so demanding that more than a third of compliant lots get scrapped or re-tested. The test was expensive in exactly the way nobody had measured.
Sample size is the lever — and 20 units is not enough

For a lot sitting just below target, consumer's risk falls as p^N. Sweeping the zero-failure sample size shows how slowly a marginal lot is caught:
| True lot reliability | Proof-pass p | N for consumer's risk ≤ 10% |
|---|---|---|
| 0.990 | 0.677 | 6 |
| 0.995 | 0.761 | 9 |
| 0.998 | 0.844 | 14 |
A lot at R = 0.998 — only a hair below the 0.999 target — needs 14 units just to push its pass probability under 10%, and far more to discriminate it sharply. The current N = 20 (dashed line) sits in the region where a marginally-bad lot still passes uncomfortably often, because the closer a bad lot is to the target, the harder it is to tell apart from a good one.
The operating-characteristic curve makes the discrimination explicit
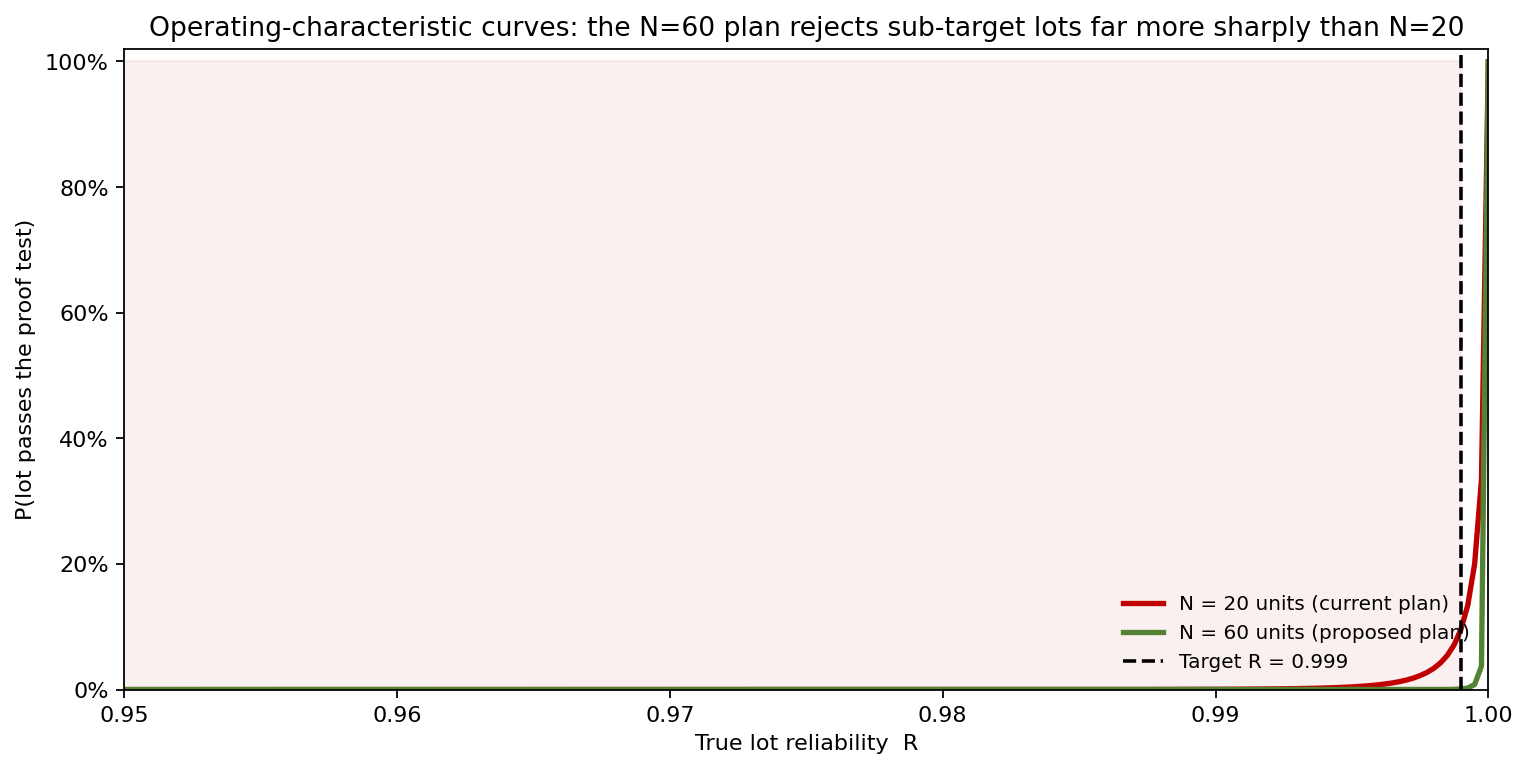
The OC curve plots P(lot passes) against the lot's true reliability — the test's ability to tell good lots from bad. Comparing the current N = 20 plan with a proposed N = 60 plan:
| True lot reliability | P(pass) at N = 20 | P(pass) at N = 60 |
|---|---|---|
| 0.9950 | 0.4% | 0.0% |
| 0.9990 | 9.6% | 0.1% |
| 0.9995 | 20.1% | 0.8% |
At N = 60 the curve drops far more steeply through the target: a lot at exactly 0.999 passes only 0.1% of the time instead of 9.6%, and a slightly-better 0.9995 lot passes 0.8% instead of 20%. Tripling the sample size turns a soft, ambiguous accept/reject boundary into a sharp one — at the cost of testing 40 more units per lot, a trade the simulation prices directly.
What drives consumer's risk
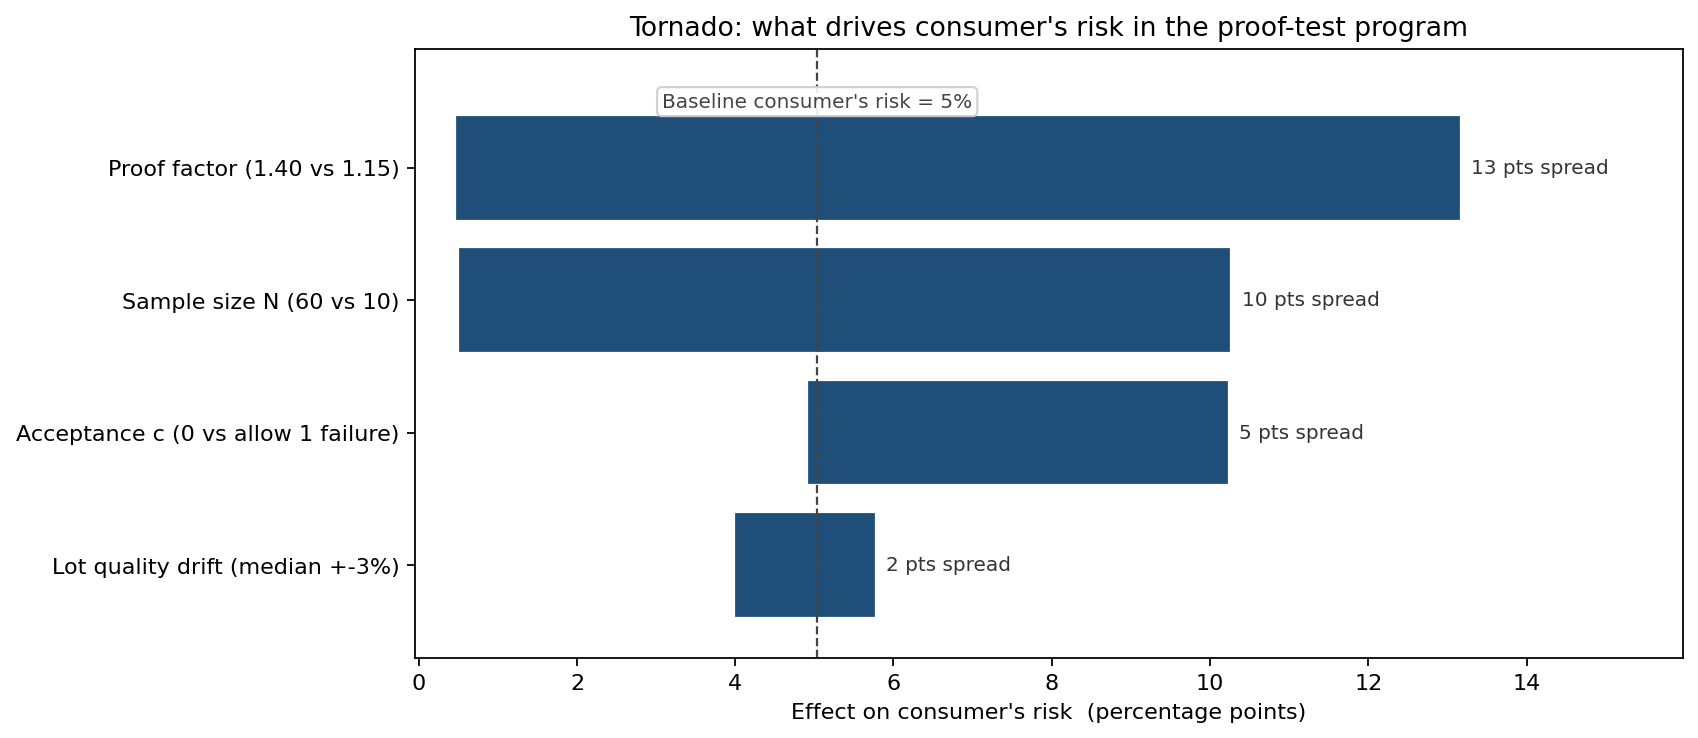
Ranking the program levers against the baseline 5% consumer's risk:
- Proof factor is the strongest lever: dropping it from 1.25 to 1.15 raises consumer's risk +8 points, while a 1.40 factor cuts it ~5 points (12.7-point spread). A harder proof load discriminates better — but also drives producer's risk up.
- Sample size (10 vs 60 units) moves consumer's risk a 9.8-point spread.
- Acceptance number — allowing one failure instead of zero — adds about 5 points of consumer's risk, the predictable cost of a looser rule.
- Lot quality drift (±3% on median strength) is a secondary effect at under 2 points.
What the model changed
- Sample size raised from 20 to 40 units with the zero-failure rule retained — chosen from the OC curves as the point where consumer's risk at the target fell below 2% without the full cost of the 60-unit plan.
- Proof factor held at 1.25 rather than increased, once the tornado showed a higher factor would cut consumer's risk but push the already-high 38% producer's risk further up — scrapping compliant lots is its own cost.
- A re-test allowance added for first-time failures, after the producer's-risk number showed how many good lots the zero-failure rule was rejecting outright.
- The qualification report rewritten to state demonstrated reliability with its consumer's risk — "R ≥ 0.999 demonstrated at a consumer's risk of 2%" — instead of a bare pass/fail, so the customer sees the confidence behind the verdict.
ModelRisk Functionality Used
- Uncertain-lot population model with per-lot LogNormal strength (median ~1.55× design, CV ~12%), so the program is evaluated against the lots the vendor could actually ship rather than one nominal lot.
- Binomial proof-test simulation drawing pass/fail counts as Binomial(N, 1−p) per lot and applying the zero-failure acceptance rule, yielding the 48.6% lot pass rate and the split between true and demonstrated reliability.
- Consumer's- and producer's-risk tracking that pairs each lot's true reliability with its test outcome — surfacing the 4.9% bad-lot pass rate and the 38.3% good-lot rejection rate a pass/fail count cannot show.
- Sample-size sweep evaluating consumer's risk as p^N across N, establishing that a marginal R = 0.998 lot needs 14 units just to fall under a 10% pass probability.
- Operating-characteristic curves for the N = 20 and N = 60 plans, quantifying that the larger plan cuts the at-target pass probability from 9.6% to 0.1%.
A proof test that a lot passes does not prove the reliability target was met — it proves only that this many units survived this load this time. Monte Carlo is what converts "it passed" into "it passed, and here is the probability that a sub-target lot would have passed too" — which is the number a qualification program actually exists to control.